
Stream Details
After you complete data ingestion, use Stream Details to view stream details and manage stream settings.
Overview
Use Stream Details to inspect schemas, apply sensitive-data redaction using regex patterns, set data retention and query limits, and configure ingestion options such as flatten level, storing original data, and enabling distinct values.
Where to find it
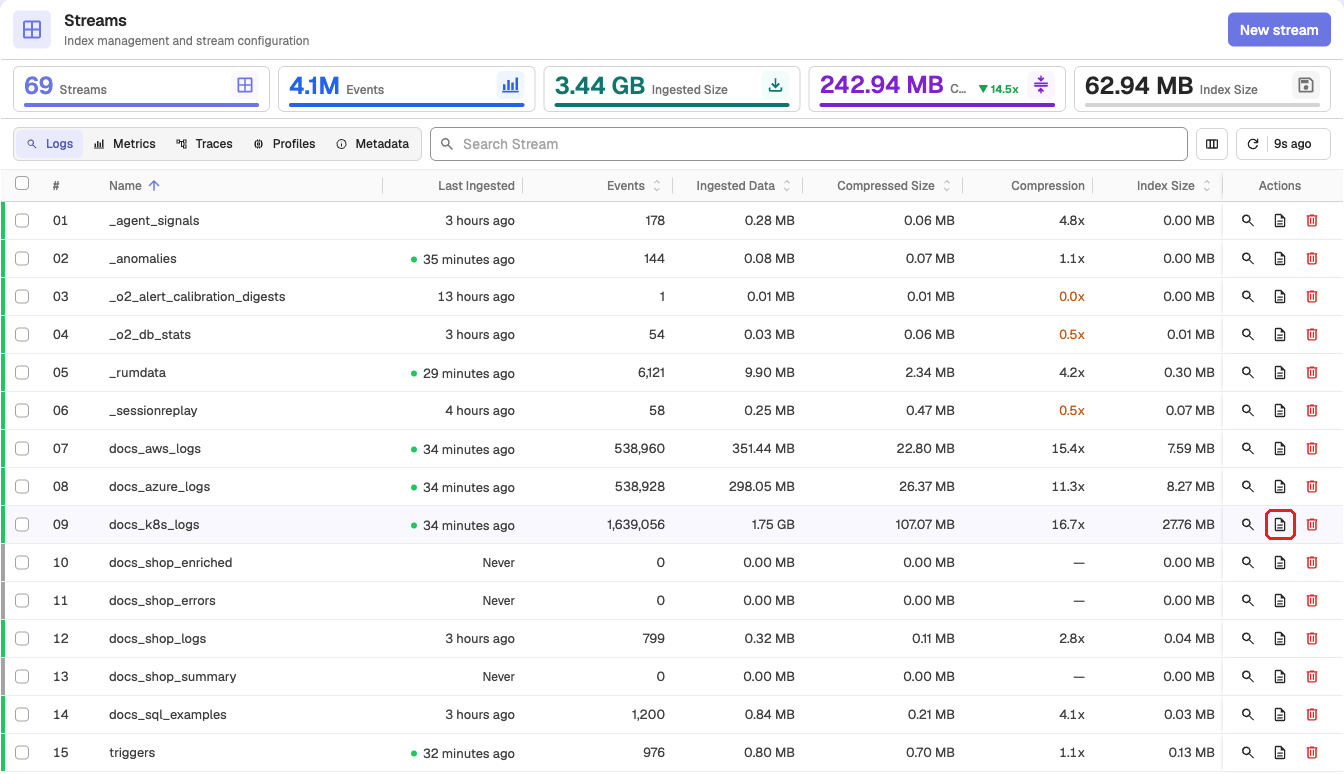
- Go to Streams.
- In the Actions column, select the Stream Detail icon. The stream details open in a side panel titled with the stream name.
Who can access it
User roles that have permission to update Streams can modify the stream settings from the Stream Details page. The permission needs to be assigned to appropriate user roles using role-based access control (RBAC).
Stream details
The header cards in the Stream Details panel show high-level status for the selected stream:
- Stream Name: Name of the selected stream, shown as the panel title.

- Events: Total number of ingested events.
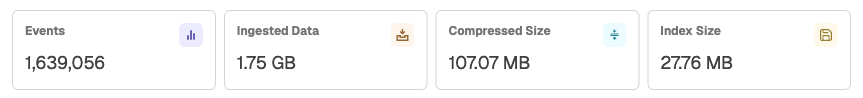
- Ingested Data: Uncompressed size of the stored data.
- Compressed Size: Storage space used after compression.
- Index Size: Size of the tantivy files generated for full text search index. Other index types, such as KeyValue filters and hash partitions, do not affect this value.
Note
OpenObserve Cloud does not show the Compressed Size and Index Size cards.
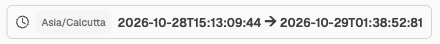
- Time range: Start time is the timestamp of the oldest data and end time is the timestamp of the newest data. If the ingested data has a
_timestampfield, it will be according to that. If the ingested data does not have a_timestampfield, then the start time will be the oldest time of ingestion and end time will be the newest time of ingestion.
Schema Settings
Inspect and manage the schema of a stream.
This tab allows you to review detected fields, assign index types, define user-defined schemas, and apply sensitive data redaction patterns.
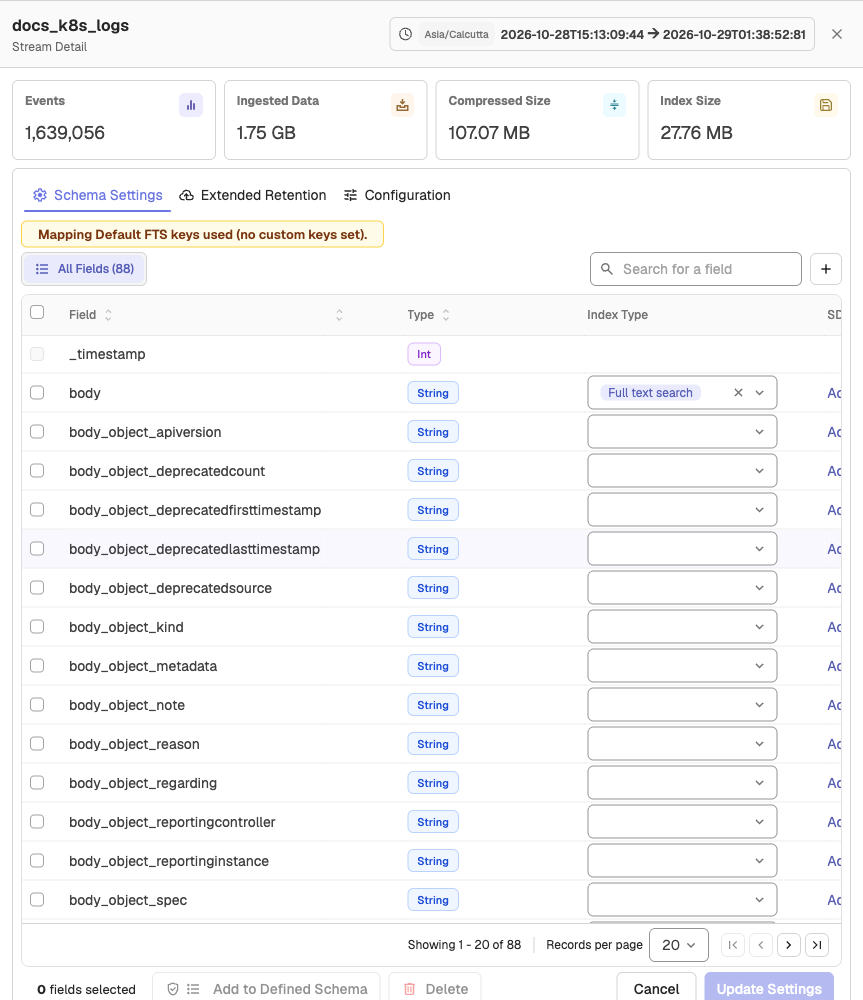
To learn more about Schema Settings, visit the Schema Settings page.
Extended Retention
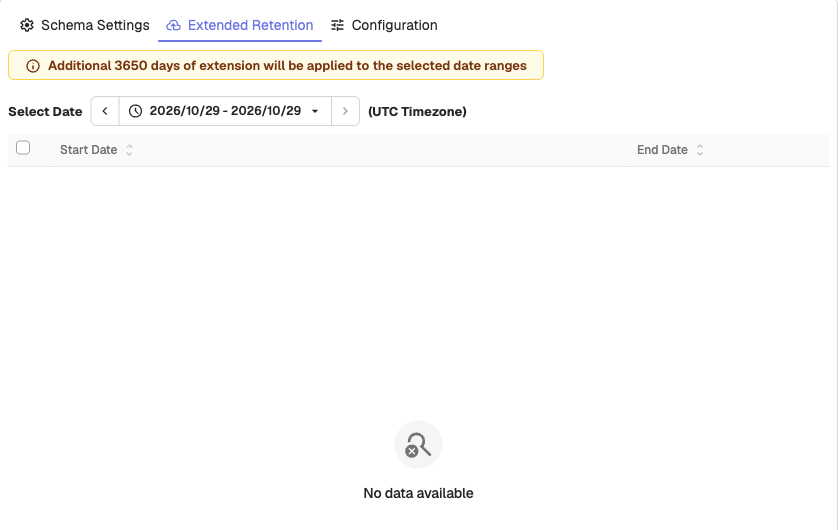 Allows you to retain specific segments of your stream data beyond the configured stream-level or global retention period. To learn more, see the Extended Retention page.
Cross-Linking
When cross-linking is enabled (ZO_ENABLE_CROSS_LINKING=true), logs streams show a Cross-Linking tab where you manage the stream's cross-links. To learn more, see Cross-Linking.
Configuration
The Configuration tab provides options to configure stream-level limits and ingestion behavior.
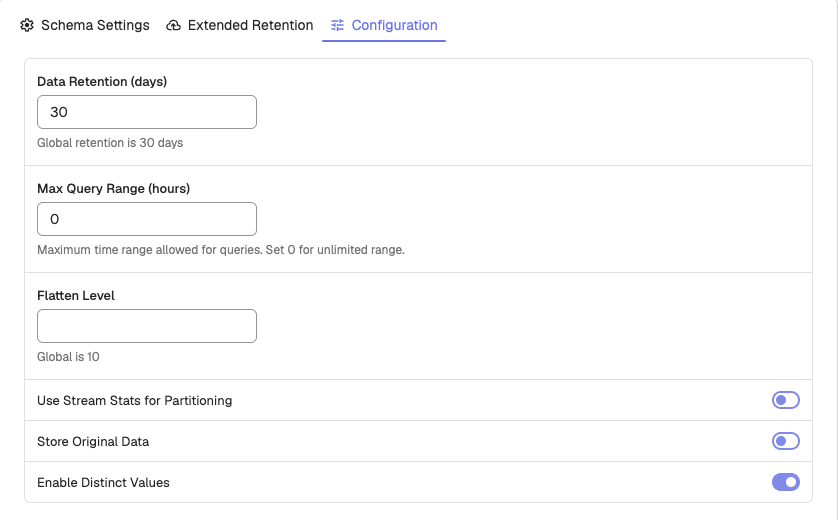
Data Retention (days)
Sets how long data is retained in this stream. If not configured, the global retention period applies. The global default is 3650 days, set by ZO_COMPACT_DATA_RETENTION_DAYS.
Max Query Range (hours)
Sets the maximum time span allowed per query. This can help reduce query load. Note that this is stream and org specific.
- You can set a global value as the maximum query range, for all streams across all organizations using the following environment variable:
ZO_DEFAULT_MAX_QUERY_RANGE_DAYS However, when a non-zero Max query range is set on a stream, the value set through Stream Details overrides the global value.
By default, both the environment variable and the Max Query Range value are set to zero, which means there is no limit.
Flatten Level
Controls how deeply nested JSON is flattened during ingestion for this stream. Flattening converts nested structures into dot-delimited keys.
- Streams can have different nesting depths. Set a suitable level here without changing the global default.
- The flatten level accepts non-negative integers. A value of 0 means no limit, all nested fields are flattened. If left blank, the stream inherits the global ZO_INGEST_FLATTEN_LEVEL. The UI displays the current global value for context.
Use Stream Stats for Partitioning
When you enable this toggle, OpenObserve assumes that all your data present in the stream is equally split and creates equal sized partitions between the start and end time.
Store Original Data
Keeps the raw, original document alongside parsed fields. This option is not shown for traces streams. Useful for audits and reprocessing. Increases storage because raw payloads are preserved.
Enable Distinct Values
Indexes the fields that dashboard variables read values from, so value lookups for those fields are served from the index instead of a full scan. On by default. To learn more, see Distinct Values.
Troubleshooting
- If stream details appear blank, verify that the data has been successfully ingested.
- Ensure you have the necessary role permissions to view or modify stream settings.
Next Steps
Streams in OpenObserve
Streams in OpenObserve define how logs, metrics, and traces are ingested, stored, and queried—essential for data processing, retention, and access control.
Schema Settings
Manage stream schemas in OpenObserve to optimize query performance. Define field types, set index types, and enable user-defined schemas for efficiency.