
Mistral → OpenObserve
Automatically capture token usage, latency, and model metadata for every Mistral AI inference call in your Python application.
Prerequisites
- Python 3.9+
- A Mistral account with an API key
- An OpenObserve account (cloud or self-hosted)
- Your OpenObserve organisation ID and Base64-encoded auth token
Installation
pip install openobserve-python-sdk "openinference-instrumentation-mistralai==1.4.0" mistralai python-dotenvConfiguration
Create a .env file in your project root:
OPENOBSERVE_URL=https://api.openobserve.ai/
OPENOBSERVE_ORG=your_org_id
OPENOBSERVE_AUTH_TOKEN=Basic <your_base64_token>
MISTRAL_API_KEY=your-mistral-api-key
Instrumentation
Call MistralAIInstrumentor().instrument() before importing the Mistral client.
from dotenv import load_dotenv
load_dotenv()

from openinference.instrumentation.mistralai import MistralAIInstrumentor
from openobserve import openobserve_init

MistralAIInstrumentor().instrument()
openobserve_init()

import os
from mistralai import Mistral

client = Mistral(api_key=os.environ["MISTRAL_API_KEY"])

response = client.chat.complete(
    model="mistral-small-latest",
    messages=[{"role": "user", "content": "Explain observability in one sentence."}],
)
print(response.choices[0].message.content)
What Gets Captured
| Attribute | Description |
|---|---|
llm_model_name | Model used (e.g. mistral-small-latest) |
gen_ai_response_model | Model that served the response |
llm_system | mistralai |
llm_provider | mistralai |
gen_ai_usage_input_tokens | Prompt token count |
gen_ai_usage_output_tokens | Completion token count |
gen_ai_usage_total_tokens | Total tokens consumed |
openinference_span_kind | LLM |
operation_name | MistralClient.chat |
span_status | OK or ERROR |
status_message | Error details if the request failed |
duration | Request latency |
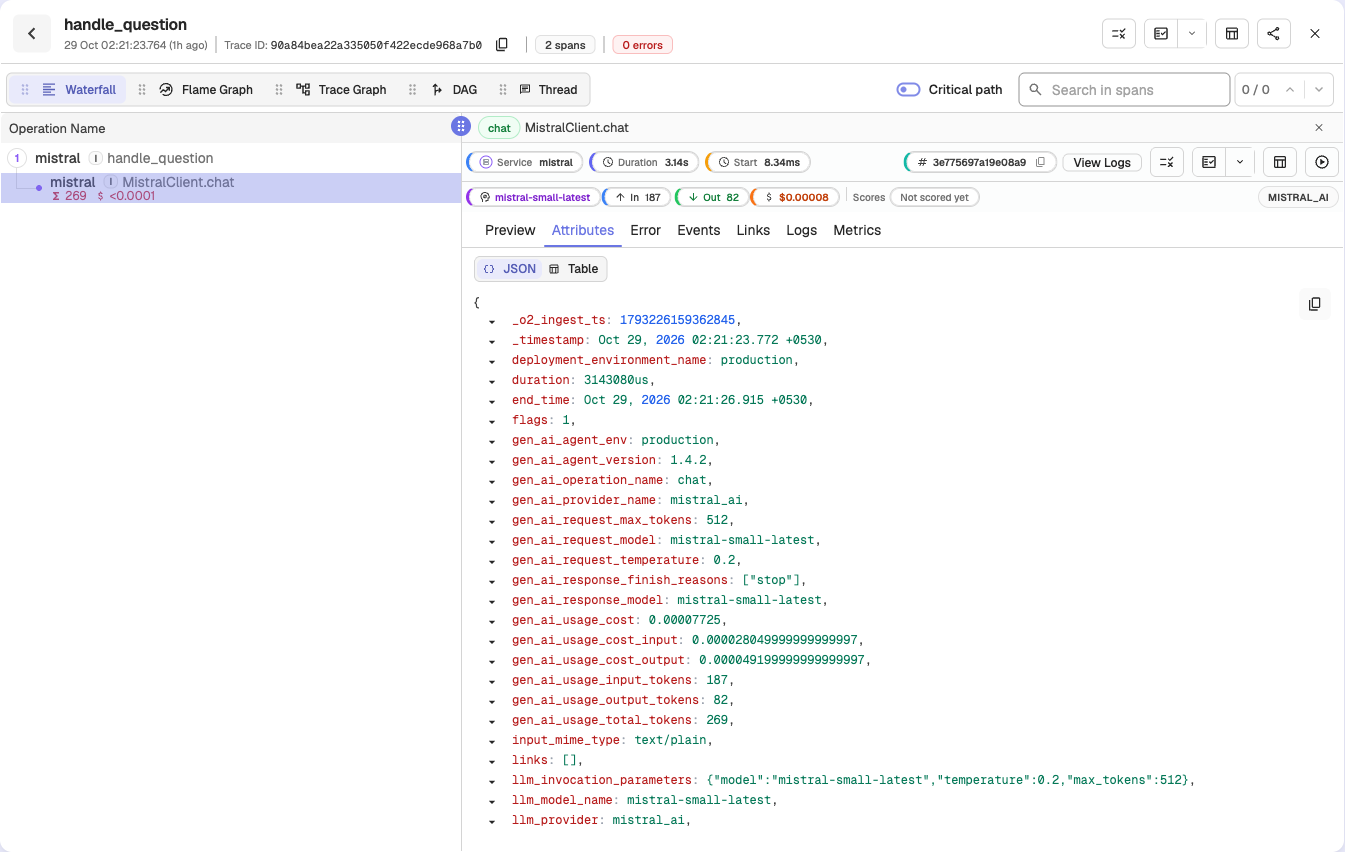
Viewing Traces
- Log in to OpenObserve and navigate to Traces in the left sidebar
- Filter by
llm_model_nameto find Mistral spans - Click any span to inspect token counts, model name, and latency
- Error spans show
span_status = ERRORwith the full error message instatus_message
Next Steps
With Mistral instrumented, every inference call is recorded in OpenObserve. From here you can compare latency across Mistral models, track token consumption over time, and set alerts on error rates.
Read More
Was this page helpful?